
TypeSafe AI Jev: Typed Decisions, Confidence, and Limits
When software needs a routing decision, generating prose and converting it back into a command can add work. TypeSafe AI’s Jev accepts context and typed questions, then returns options, scores, or probabilities. Assess both speed and the division of work between model and code. Understand confidence, calibration, and type safety before using its decisions to affect people.
What is Jev and what kind of problems is it suitable for?
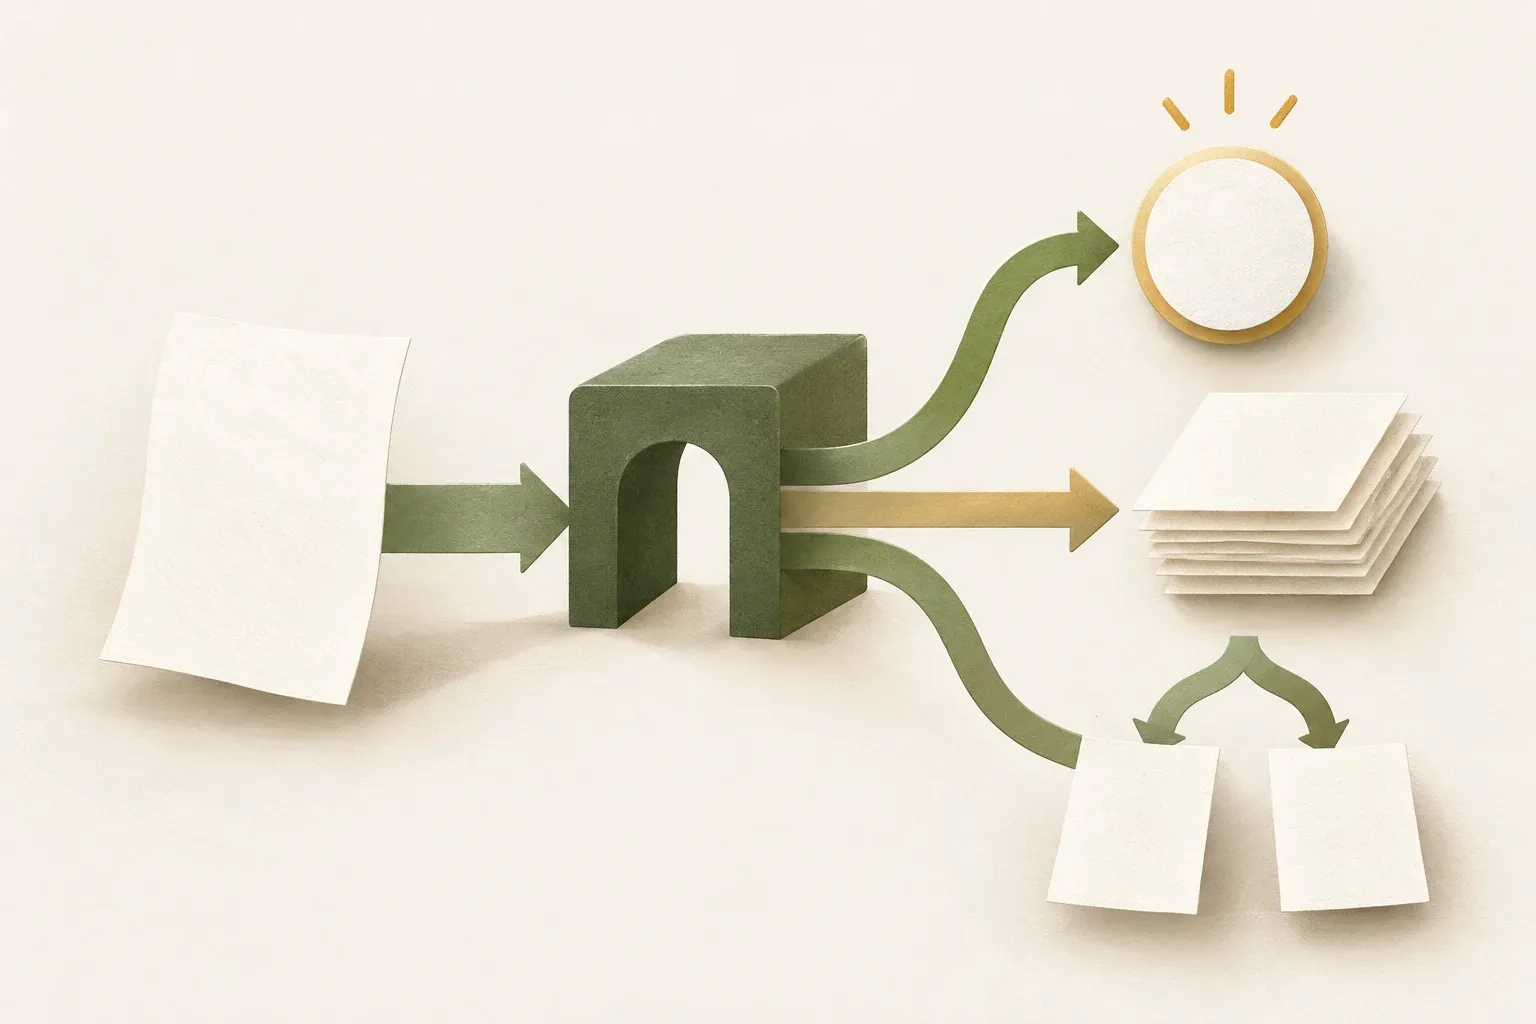
Jev is a TypeSafe AI model that accepts context and typed questions, returning answers software can use directly. such as selecting a category from a list, scoring against criteria, or assessing the probability of a yes/no answer. The documentation calls this model group System One models and positions Jev as the company's main model. See Jev Description from TypeSafe
Imagine a support system receiving, “My resized image is blurry; I want a smaller file but readable text.” It must identify images, quality concerns, and the relevant guide. A category code and confidence level serve the program better than paragraphs of explanation. Jev is designed for these smaller decisions.
Separate deciding from acting. Jev does not have permission to read the database, send money, or delete files because the action name was returned. The program around the model must check permissions, check conditions, and call the tool itself. The reliability of the system therefore depends on both the model and the code design.
KrobClick suggests assessing how well Jev replaces rules brittle to human language, such as detecting differently worded intentions. Calculations, amounts, file sizes, and precisely defined conditions should still use ordinary code.
The Models page checked October 29, 2026 also lists Jev 1.14 (jev-1.14.0), released October 14. This article retains its Jev 1.13 API example and version-specific jaggedness discussion; it does not establish whether those issues persist or are fixed in 1.14. Re-evaluate the same data and thresholds before switching versions.
What can System One and RLCD tell us?
TypeSafe uses fast, immediate System 1 thinking as an analogy for narrow decisions. Jev refers to William Stanley Jevons and the idea that lower resource costs can increase demand. These explain the naming, not proof of brain simulation or economic laws. See Launch announcement and name description
The company describes its training approach as Reinforcement Learning for Calibrated Decisions, or RLCD emphasizing structured answers and probabilities aligned with actual outcomes rather than prose people like reading. Documentation compares this with RLHF's human-preference feedback and RLVR's verifiable-outcome rewards. This explains TypeSafe's approach, not identical behavior across all models within each group. See AI primer and RLCD concept
The word calibrated describes a property across many predictions. Hypothetically, in a well-calibrated system, events assigned probability 0.8 should occur about 80% of the time. This does not guarantee any one case; retest calibration for new languages, domains, and criteria.
The cited documentation supports input/output formats and the developer's description of training methods This article did not inspect weights or training data or reproduce training. API appearance alone cannot establish that the architecture is renamed BERT or entirely unrelated to language models.
Differences from structured outputs need to be measured beyond JSON output.
TypeSafe emphasizes decision models and parallel result delivery. KrobClick suggests comparing it with schema-supporting LLMs based on each service's guaranteed capabilities. Comparing only against a chat request to “reply in JSON” does not establish that all alternatives lack format control. Structural JSON validity and prediction accuracy are separate evaluation dimensions.
Ask at least three questions: Are answers always in the allowed set? Do probabilities align with outcomes? How much faster or cheaper is the full workflow for the same task? Similar-looking outputs do not prove performance on these separate dimensions.
What is the difference between Choice, Score and Noul?
| type | Suitable tasks | What is returned | What to watch out for |
|---|---|---|---|
| Choice | Choose a category or action from a defined set | Options, probability of every option and confidence | Cover the relevant options, including out-of-category cases |
| Score | Evaluate one dimension along an ordered scale. | Weighted average score, distribution, and confidence | A position on the defined scale, not a physical unit |
| Noul | Check the yes/no condition statement. | A value from 0 to 1 representing the probability of yes | A midpoint indicates uncertainty, not “none” |
Choice: Choose from the options accepted by the program.
If the question is “Is this about PDFs, images, QR, or something else?” use Choice, explaining what each category means. The options are in no particular order. and the answer is in the given set. The API documentation specifies an upper limit of 255 options per question. See Choice and API requirements
KrobClick suggests providing an exit such as other or “Insufficient information” when the task permits out-of-category cases. Correct answer types help only when the answer set covers real-world possibilities. If the only choices are PDF and QR, a message about images may still be forced into the wrong category.
Score: The numbers have meaning according to the level description.
Score uses an ordered scale, with levels numbered from 0 by list position. Scores may fall between levels. 0 × 0.1 + 1 × 0.6 + 2 × 0.3 = 1.2 Watch How to interpret the score and writing grade level
A score of 1.2 does not mean 1.2 hours of waiting or 1.2 damage units. Averages also hide uncertainty: all probability at level 1 and half each at levels 0 and 2 both average 1 but differ greatly. Read distributions alongside scores and use distinct scenario descriptions rather than numeric thresholds alone.
Noul: The probability of a yes answer.
Noul suits a single well-defined question, such as “Did the user request escalation to a person?” Values near 1 lean yes, near 0 lean no, and near 0.5 indicate uncertainty. This answer type has no field confidence separately. See Noul
You must write conditions that match what you want to check. “Message indicating whether payment has been made” can check what the user said. But it does not confirm that the transaction actually happened. Confirming a transaction requires reading information from an authorized source, such as a payment system.
Probability and confidence must be read separately.
In Choice and Score, the value probabilities is the probability distribution, while confidence is a statistic calculated from that distribution to summarize certainty. The documentation does not define confidence as each answer's accuracy rate. See Definition and confidence formula
For Choice with n options. The formula is (p_max − 1/n) / (1 − 1/n) where p_max is the highest probability. A hypothetical three-option result of 0.8, 0.15, and 0.05 has confidence of (0.8 − 1/3) / (1 − 1/3) = 0.7 Do not read confidence 0.7 as “70% probability this choice is correct”: the model's assigned probability for that option is 0.8.
Score accounts for distances between levels, so uncertainty between adjacent levels differs from a split between extremes. Noul directly uses the probability of yes. KrobClick suggests thresholds specific to the question and its consequences, then checking actual error rates among accepted cases. Do not adopt example thresholds as standards without testing.
Also distinguish Model certainty with Is the information complete enough to work? A model may be certain that the user wants deletion while lacking the file identity or permission to delete it. Check these separately; raising a confidence threshold cannot replace authorization or confirmation.
Example API for classifying tool requests
The HTTP request uses POST https://api.typesafe.ai with authentication and three main parts: state, model and questions This JSON example was created by KrobClick to explain the documented structure. We have not submitted it to the service or connected Jev to the site. API reference We have not submitted this example to the service or connected Jev to the site.
{
  "state": {
    "message": "อยากลดขนาดรูปให้ส่งได้ แต่ไม่อยากให้ตัวหนังสือเบลอ"
  },
  "model": "jev-1.13.0",
  "questions": {
    "tool_family": {
      "type": "choice",
      "instructions": "Choose the tool family relevant to the user's request.",
      "criteria": {
        "image": "Resize, compress, or convert images.",
        "pdf": "Work with PDF documents.",
        "qr": "Create or read QR codes.",
        "other": "None of these fits, or the request is unclear."
      }
    },
    "preserve_readability": {
      "type": "noul",
      "instructions": "Does the user explicitly ask to preserve text readability?"
    }
  }
}
We use Thai text in state and an English question to show that the two have different roles This is not proof that this language combination method is the most accurate. Test Thai questions on real task data before choosing. The name tool_family is the key used to match answers. The API documentation says question names are not sent to the model for inference, so describe the meaning in instructions and criteria completely
State can be plain text or JSON with contextual fields. Send only what the question needs, such as the text to classify and relevant facts, instead of the full user history. See State management approach After receiving the answer, the program checks that its category is allowed, meets tested thresholds, and has enough information before displaying a guide or next route.
The official Python SDK example sends a state and a Choice question, then reads the selected option.
from typesafe_sdk import Choice, TypeSafeClient

with TypeSafeClient() as client:
    response = client.system_one(
        state={"document": "I was charged twice. Please fix this ASAP."},
        questions={
            "category": Choice(
                instructions="What is this ticket about?",
                criteria={"billing": None, "technical": None, "other": None},
            )
        },
    )

print(response.choices["category"].choice)
Compare this example with the HTTP JSON above. SDK and HTTP field formats may differ. We have not run this example, so it is not evidence of Jev’s accuracy. Source: Source documentation · MIT
Ask several questions at once, then use code to select relevant results
TypeSafe supports multiple questions about one state in a single request, evaluating each independently in parallel. The documentation proposes speculative fan-out: Ask all potentially needed conditions together, then let code select only results relevant to the actual path. See Speculative fan-out
Hypothetical support triage may ask concurrently whether a request is technical or general, blocks core work, and has reproducible steps. If nontechnical, reproduction results can be ignored. This reduces sequential waiting but adds question detail and still consumes the token budget; it does not allow unlimited free questions.
Questions that are evaluated separately do not receive responses to other questions as context within a single request. If B depends on a result from A that does not yet exist, design B to read the condition directly from state, or make it a separate request after A's result is known. Sending both together does not automatically create a causal chain.
KrobClick proposes separating model decisions from calculations in code. For task prioritization, a model might assess impact and urgency independently. Code then normalizes each score to 0–1 and combines them using team-defined weights. That formula is an inspectable system policy; the model should not invent weights per request.
If two properties can coexist, such as “about images” and “about PDFs,” consider multiple Noul questions or separate tasks instead of one single-category Choice. Question format is part of problem definition, not something a smarter model alone fixes.
Where it fits in AI agents and RAG
Documents suggest Jev as a workflow router, directing requests to database searches, specialist models, or humans without a large generative model at every decision. See Intent routing
An agent system may let a model plan or propose tools, then ask Jev a narrow question such as “Is this action relevant to the stated goal?” before code checks the tool allowlist. Another model does not automatically ensure safety: both may be influenced by the same data. Permissions and non-model-dependent result checks remain necessary. Read more in Zero Trust design for AI agents
For Retrieval-Augmented Generation, or RAG, KrobClick suggests trying Jev after initial document retrieval to assess how directly each item answers the question, then passing only qualifying items to the model for drafting. Assess “relevance” separately from “reliability” and “freshness”: a highly relevant document can still be inaccurate or outdated.
Document extraction offers another clear example: a parser first finds actual email addresses or amounts, then Jev selects the candidate matching the required role. Code copies the selected value instead of having the model retype it. Examples appear in Pre-parsed value extraction of the developer. A limitation is if the candidate search stage misses the correct value. The selection step cannot recover values that do not exist in the list.
Read benchmarks and calculate costs
TypeSafe advertises 193.6× faster and 444.6× cheaper workflow evaluations, noting these likely represent the high end of actual benefits. Developers report 70–500 milliseconds, generally tested from the western US, not guaranteed turnaround for Thai users. See Effects and limitations of the launch announcement
Page Workflow evals Describes evaluation of four workflows, with code enforcing rules and models answering subquestions. Reference values come from aggregated large-model answers, not human-verified facts in every case. The appropriate conclusion concerns workflow execution and agreement with that reference under those conditions. Good agreement does not guarantee alignment with experts in our domain.
Price as of document inspection date: Page Models Quotes $0.042 per million input tokens with no output-token charge. Hypothetically, one million requests averaging 2,000 input tokens including state and questions total 2 billion tokens. At this rate, processing costs 2,000 × $0.042 = $84 not $0.042 for one million requests
The $84 excludes retries, infrastructure, intermediary providers, taxes, currency conversion, and human review. Test actual Thai token counts. If preprocessing reduces input, include its cost too.
KrobClick suggests comparing Jev, existing rules or classifiers, and an LLM supporting structured outputs on the same task, using identical data and answer definitions. Measure error rate, average latency, p95 latency—the time within which 95% of requests finish—and total cost per correctly completed case. Cheaper individual decisions that require more human review may not reduce costs across the whole system.
Jev 1.13's limitations that must be designed to deal with
TypeSafe has a page for Jev 1.13 jaggedness reviewed October 2, 2026, identifies issues in mathematics, date comparisons, literal interpretation, excess irrelevant data, leading content, and option order. These details matter more than an isolated no-hallucination claim.
- Counting and calculating: Let code count items, calculate interest, and validate numerical ranges. Use models only for semantic decisions difficult to define in code.
- Date and time: Separate intent or date-component interpretation from time-range comparisons; let code handle calendars, time zones, and Buddhist/Gregorian years
- Too much context: Context capacity does not guarantee accuracy. Remove irrelevant content before sending.
- Manipulative text: Test inputs that order the system to ignore criteria or assign themselves a category. Responses must not bypass authorization checks.
- Sensitivity to option ordering: Reorder the candidates and check that answers remain consistent for the same examples
Restricting answers to an allowed set prevents invented category names, but the model can still choose the wrong member. In a hypothetical approval task, “Approve” may satisfy the schema while approving the wrong person. Measure semantic accuracy separately from format compliance. You can still choose the wrong member. A hypothetical example: “Approve” is a response that passes the schema, but approving the wrong person is still a business mistake. Semantic accuracy must therefore be measured separately from the rate at which the response format passes.
According to the reviewed Models page, the model accepts text, not direct image, audio, or video input. The total request budget is 64k tokens, with state plus the longest question capped at 32k. See Current version limits The task of reading images therefore must first be converted into text or data. This may create more errors from the beginning.
The 64k request limit and 32k state-plus-one-question limit are defaults for both 1.13 and 1.14. Documentation also offers an opt-in long-context header raising both limits to 262k tokens. Greater accepted context does not establish accuracy; start with defaults and inspect actual request token counts before considering that mode.
Thai-data test plan
TypeSafe states that English is the main language of training and provides the best accuracy to date. Other languages are acceptable but the quality is not the same. See Language support We therefore cannot conclude that Jev is accurate in Thai merely because its API accepts Thai text
The following plan is KrobClick’s proposal, not a benchmark we have run. Start with reversible mistakes, such as suggesting guide categories, before tasks with greater user impact. Start with reversible errors, such as suggesting manual categories, before tasks with greater user impact
- Define your answer before choosing a model: Write examples that fit, do not fit, and lack sufficient information so reviewers share the same definitions. Ambiguous cases should have an escalation path to human review.
- Create examples reflecting actual use: Include formal and colloquial Thai, omitted words, mixed Thai and English, negation, and multiple needs in one message. Use synthetic or de-identified data.
- Separate question-tuning data from final evaluation data: Use the first set to select criteria and thresholds, then freeze them before evaluating the other. Avoid repeated prompt tuning that memorizes test answers.
- Measure results by category: Check precision within assigned categories and recall of cases that belong there. Count cases needing human review. Overall accuracy alone can conceal poor results in rare categories.
- Check the probability: Group answers by probability range and compare actual outcome rates, showing sample counts. Small groups yield uncertain calibration estimates. Keep this check separate from confidence.
- Measure after setting thresholds for human review: Report both the share of tasks automated and the error rate within that share. Accuracy achieved by handing almost everything to humans is less useful than greater automation at the same risk level.
- Test conditions to fail: Reorder options, add irrelevant text and leading instructions, and simulate timeouts or unavailable services to make sure fallback paths actually work
Include hypothetical cases such as “I do not want to convert a PDF; I want to shrink the images in it” and “I do not need a new QR code; please read the existing one.” These contain several category keywords but require intent interpretation. “The file is too large to send” lacks a file type; a follow-up question may be more useful than confident classification.
Privacy and deployment
Jev API use sends state from the caller's system to the provider. TypeSafe says inputs are not used for training or fine-tuning, but this is not the same as no retention. Its Legal documentation separately offers enterprise zero data retention. See Privacy Policy and Legal and ZDR You should check the contract terms applicable to real accounts before submitting customer information.
This article does not add Jev calls to KrobClick. For a site designed to keep files in the browser, external decision services change data flows and require separate consideration. Do not send files, documents, or user history to an API merely to try a model.
For an external system, KrobClick recommends calling the service through a component that securely stores API keys, limiting transmitted data, checking permissions before acting, and preparing a fallback when the service is unavailable. Keep only the records necessary for quality checks, without unnecessarily logging secrets or personal data.
In terms of repeatability, the Models page specifies aliases like: jev-latest changes versions with releases, and responses return the actual model name. If thresholds were tuned to a version, pin it and retest before upgrading. See Aliases and versioned model IDs KrobClick proposes shadow mode—letting the model respond without taking real actions—to identify errors before granting automated permissions.
Criteria for choosing Jev
| Job description | How to start evaluating | Reason |
|---|---|---|
| Calculate amounts, count files, compare dates. | Inspectable code and libraries | Clearly defined answers with directly testable boundaries |
| Stable classification tasks with abundant labeled data | Existing rules or classifier as a baseline | may already suit your costs, privacy needs, and task requirements |
| Frequent semantic decisions with clearly defined options | Compare Jev with the baseline | Match the answer contract and evaluate the model's sub-questions. |
| Write articles, explain reasoning, generate code or long plans | Text-generation model with result validation | Requires open-ended output; a complete answer set cannot be specified beforehand |
| Actions that affect money, rights, or important information | A workflow with permission checks and risk-based confirmation | Judgment from the model alone is not sufficient for approval. |
This table is KrobClick’s assessment framework. Jev gives semantic questions a software-oriented interface with defined answers and probability distributions that can fit into workflows. Measure benefits on the actual task, including data preparation and review costs.
Teams can start with one decision, build a Thai test set with ambiguous cases, compare against the existing method, and provide a fallback for uncertainty. Expand only if Jev reduces time and cost while maintaining an acceptable error rate. The speed of a model is useful when the system around it knows where to believe, apply results, and stop.
Sources
- TypeSafe AI: Introduction
- TypeSafe AI: Introducing System One Models & Jev
- TypeSafe AI: AI primer and RLCD
- TypeSafe AI: Choice
- TypeSafe AI: Score
- TypeSafe AI: Noul
- TypeSafe AI: Confidence and calculation formula
- TypeSafe AI: HTTP API reference
- TypeSafe AI: Models, pricing, limits, and languages
- TypeSafe AI: State
- TypeSafe AI: Speculative fan-out
- TypeSafe AI: Intent routing
- TypeSafe AI: Pre-parsed value extraction
- TypeSafe AI: Workflow evals and assessment methods
- TypeSafe AI: Jev 1.13 jaggedness
- TypeSafe AI: Legal and ZDR conditions
- TypeSafe AI: Privacy Policy
- typesafe-ai/typesafe-sdk-python
Models and limits additionally reviewed October 29, 2026; Jev 1.14 is now listed. Request examples stay pinned to Jev 1.13, and jaggedness findings are specific to that version. This is documentation analysis, not API testing. Numeric examples are hypothetical; pricing and terms may change.