
Zero-trust AI Agents: Intent Checks and Execution Controls
An API call may be correct character for character yet violate user intent. This matters for agents issuing refunds, changing databases, or sending data. Zero-trust runtimes inspect content, intent, and behavior across multiple turns, beyond syntax alone.
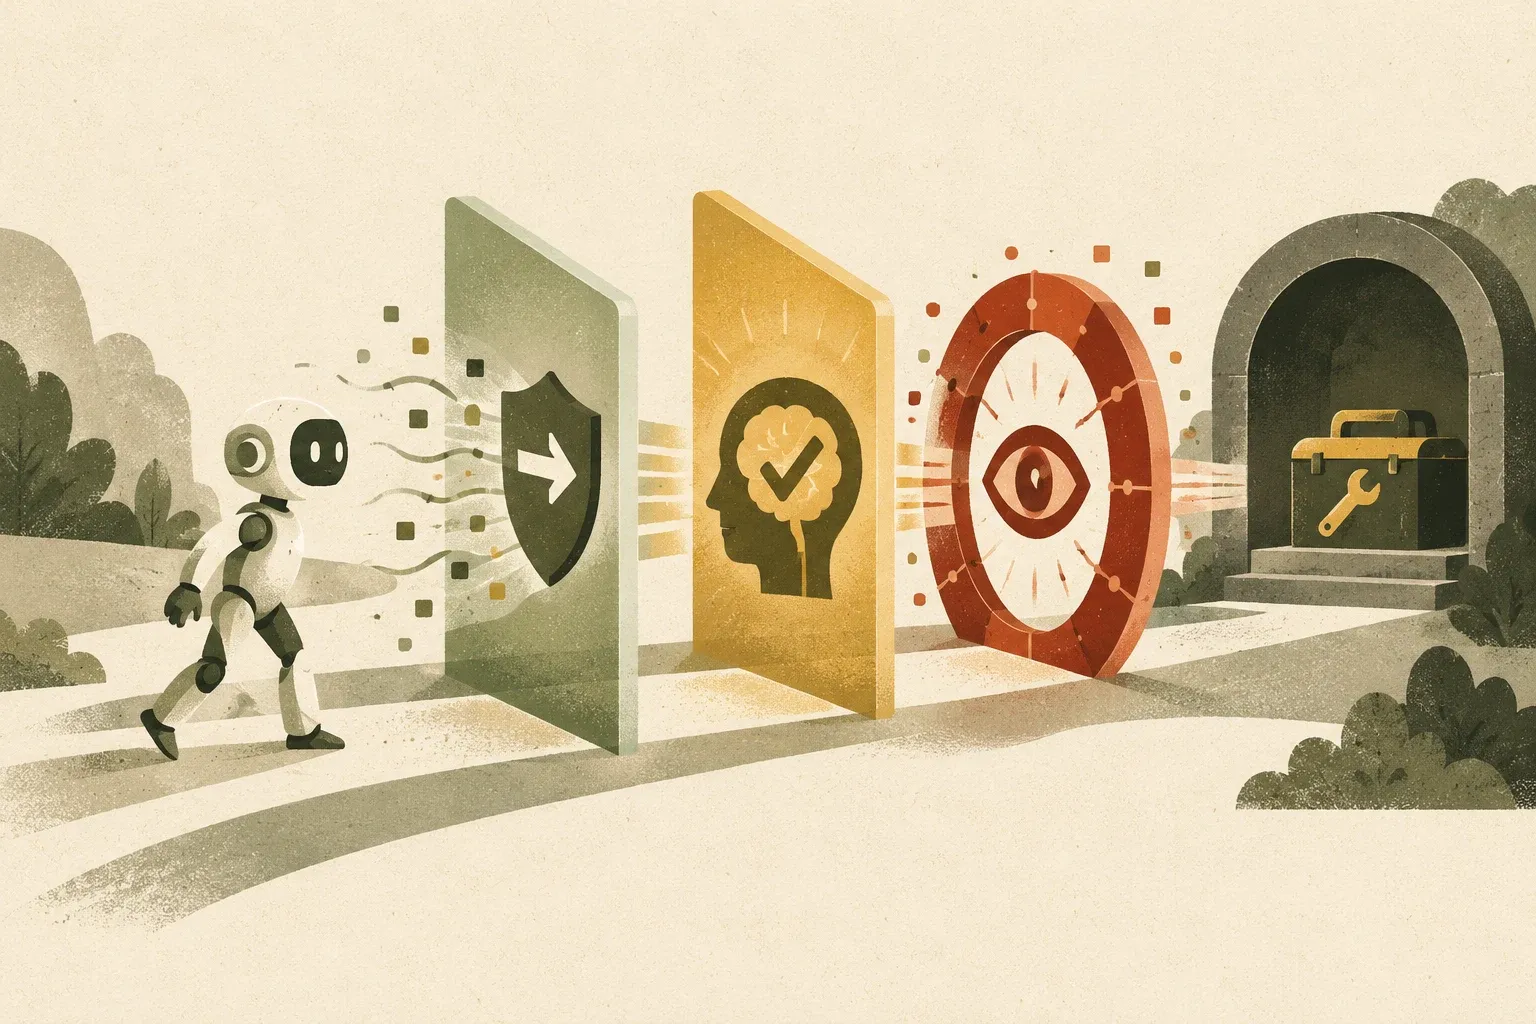
Zero-trust checks permissions and context for every action
Zero trust does not grant access merely because a request originates from a previously trusted component; each action is checked against context and required permissions. AI agents complicate this by translating natural language into tool calls. A valid schema can still result from misunderstanding, prompt injection, or manipulation into unintended actions.
A parser may verify a refund amount and account are present without knowing which item was returned or whether repeated smaller requests evade limits. Systems need meaning and history, not syntax alone.
Three control layers serve different purposes
- Filter prompt and response: Check for injection prompts, jailbreak, dangerous URLs, and sensitive data before entering the agent cycle.
- Semantic policy: Evaluate proposed tool calls against user intent and business rules before execution.
- Check for abnormalities: Continuously look at logs and telemetry to find behavior where individual requests appear normal but collectively appear abnormal.
Google cites Model Armor, Semantic Governance Policies, and Agent Anomaly Detection for different layers. No single layer sees everything: payload filters lack full business context, and per-request policies may miss cumulative cross-session patterns.
Policy should be enforced outside of agent controlled code.
If safety rules live in prompts or functions the agent can modify, attackers may find a way around them. Enforcement at the gateway or platform separates agent development from safety administration and allows a policy to cover multiple agents.
Platform policies need versions, reviews, tests, and rollback just like code. Natural-language rules may be interpreted too broadly or narrowly. Test attacks and legitimate tasks that should remain allowed.
Identity, sandbox, and signature are still required.
Intent checks do not replace deterministic controls. Agents need their own identities, least privilege, signing or authentication for writes, and sandboxed execution of generated code. Semantic rules bridge the gap between valid request structure and whether an action should occur.
For actions affecting money, personal data, or important systems, retain human approval with the recipient, amount, and reason visible before confirmation. AI reviewing another AI does not remove the need for people at every decision point.
For anomaly detection, consider false positives and information contained in logs
Anomaly detection may spot repeated refunds or access at unusual times, but both false alarms and missed events remain possible. Define which signals trigger notifications, reduced permissions, or a stopped session.
Behavior-analysis logs may contain prompts, tool arguments, and customer data. Set retention, redaction, access rights, and processing location. Do not improve security visibility by creating an unprotected sensitive-data source.
Hypothetical policy caps total refunds for one task at 10,000 baht. An agent proposes three 4,000-baht refunds. Each may pass schema and per-request limits, but totals 12,000. External controls must track cumulative amounts and pause for review beyond policy, rather than trust model explanations. These are control-design examples, not defaults or product tests.
For system tests, KrobClick proposes simulating an unavailable policy service, expired decisions, and changed amounts or recipients after approval. High-impact actions should pause when authorization cannot be established, and actual execution parameters must be checked again. An earlier approval must not cover a changed request. These are design criteria, not certification of Google services.
Start with a map of high-impact actions
Before building or buying monitoring, inventory tools and rank impacts. Define policy owners, confirmation points, and anomaly signals. Test prompt injection, transaction splitting, credentials used by the wrong agent, and policy-system outages.
Zero-trust AI Agent is an approach to layered controls that assumes models, inputs, and tool calls can fail. The system should detect anomalies, limit their impact, and retain evidence for later review.
Sources
- Google Developers Blog: Build zero-trust AI agents that judge intent, not just syntax
- OWASP Cheat Sheets Series Team
This article refers to Google Cloud guidelines and services as of 7 October 2026. An example architecture is used for explanation. It is not evidence that all systems have complete risk control. Threat modeling and independent testing should be done before actual use.