
EmbeddingGemma 2: Multimodal Search and Memory Trade-offs
EmbeddingGemma 2 is Google DeepMind’s multimodal embedding model. It maps text, code, images, video, and audio into a shared vector space for search and comparison across data types, with a model size designed for on-device use.
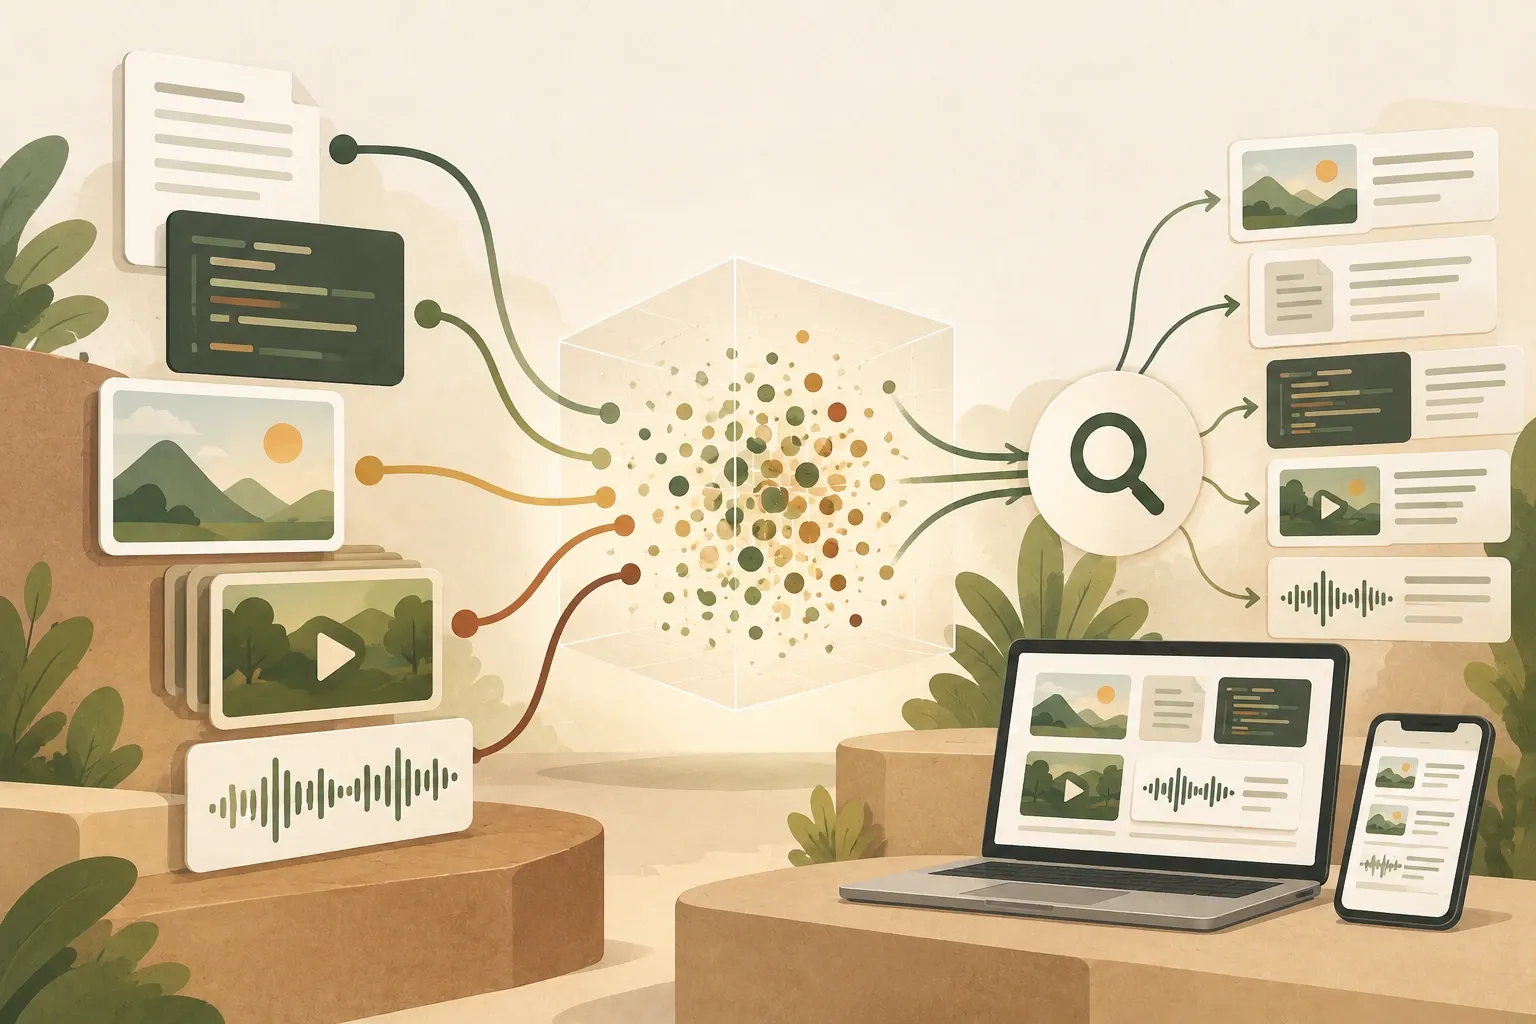
What is EmbeddingGemma 2 and how is it different from AI that generates text?
EmbeddingGemma 2 is a model for creating embedding or numerical vectors representing the “meaning” of data. Their main function is not answering questions or generating text like chat models. When two pieces of data have similar meanings, their vectors tend to lie close together in mathematical space, supporting search, clustering, recommendations, and Retrieval-Augmented Generation (RAG).
Google's focus in this release is on combining multiple data types into one area. EmbeddingGemma 2 supports text, code, images, video, and audio and converts them all into a vector space of 768 dimensions, making it possible for text queries to be used to search for images, video, or audio based on their “meaning” without necessarily converting everything to text first.
How search works across data types in one vector space
A conventional multimodal search pipeline may transcribe speech or caption images before embedding the resulting text. These conversion stages add processing time and complexity and can lose information.
EmbeddingGemma 2 uses a separate encoder for each modality with a shared output vector space. Users can search video moments with “someone assembling a bicycle,” or use an image to find related images and clips.
740M parameters does not mean all must load every time
- Text and code: The base component uses approximately 270 million parameters and supports a context of up to 8,192 tokens
- Pictures and videos: adds a vision encoder with approximately 170 million parameters, bringing text + vision to approximately 440 million parameters
- Audio: The audio encoder has approximately 300 million parameters, so the text + audio set is approximately 570 million parameters.
- Full multimodality: With all components combined, the model has approximately 740 million parameters
This modular design matters on-device because apps need not load unused encoders. Google reports active RAM for text-only weights after quantization as low as roughly 191 MB on Pixel 11 Pro, versus about 567 MB for the full multimodal model. Treat these as results on Google's hardware and settings, not guaranteed figures for every device.
8K Context and search across text, images, video, and audio.
EmbeddingGemma 2 expands the context window to 8K tokens, which Google says can support up to approximately audio 5.5 minutes, 29 images, or 58 video frames, depending on the input format and token allocation within the model.
Long or multi-part inputs can be embedded without always splitting them into very small pieces. Developers still need task-appropriate chunking: a larger context does not guarantee better search when everything is sent at once.
How do Matryoshka Embeddings reduce storage?
The default output has 768 dimensions. Matryoshka Representation Learning (MRL) allows reduction to 512, 256, or 128 without retraining, trading some quality for storage and retrieval speed.
Google's guide says one million 768-dimensional bfloat16 vectors use about 1.5 GB, versus about 250 MB at 128 dimensions, roughly six times smaller. Queries and documents must use equal dimensions; truncated vectors should be renormalized before cosine similarity.
KrobClick proposes a test using Thai queries with known target results, including exact matches, synonyms, and unanswerable cases. Keep documents, chunking, and criteria fixed while comparing 768- and 128-dimensional vectors, matching query and document dimensions within each run. Record whether expected results appear in the chosen top results, along with index size and retrieval time. Smaller vectors alone do not establish equal quality. This plan has not been run on the model.
Those storage figures approximate the vectors alone, not the full database. At two bytes per bfloat16 dimension, one million 768-dimensional vectors require 1,536,000,000 bytes; 128 dimensions require 256,000,000 bytes, a sixfold difference. Indexes, metadata, and copies add space, so measure the actual system separately.
Code quality has improved, but benchmarks aren't the whole answer.
Google reports EmbeddingGemma 2's MTEB Code score rising from 68.76 to 78.68, approximately a 14% relative improvement, while multilingual text capabilities remain near the previous model's level.
Benchmarks compare models under a shared test setup; they do not directly predict improvements for an organization’s search system. Results also depend on the data, queries, document chunking, and evaluation criteria.
What kind of work is EmbeddingGemma 2 especially suitable for?
- Search for local files: Search for images, documents, audio, or video using natural language. It stores both the embedding creation and the database on the device.
- Local RAG: Use EmbeddingGemma 2 to retrieve context and send relevant information to an answer-generating model such as Gemma 4, reducing private-file uploads to the cloud
- Find the code: Use plain descriptions to find functions or files by purpose, useful for codebase indexing and agents retrieving code references
- Find a range in video or audio: Create embeddings from video frames or audio segments, then search using text or another media type
- Classification and routing: Compare input embeddings with category descriptions for zero-shot task routing in some cases
The advantage of on-device is privacy. But this does not automatically make the system secure.
Local embedding computation reduces the need to send raw data to servers, benefiting private data and offline work and potentially reducing latency for repeated searches
Local execution does not solve every problem. Models may misrank results, exhibit bias, or retrieve unauthorized information if access control is weak. Google's model card says developers must evaluate downstream applications and add context-appropriate retrieval filtering and fairness testing.
What to understand before choosing
EmbeddingGemma 2 combines multiple modalities in a model below 1 billion parameters. Choose based on the data your app retrieves, offline needs, and acceptable trade-offs between quality, memory, and vector storage. Text-only work may suit the text encoder alone, while combined image, audio, and video search benefits more from a shared embedding space.
Test retrieval quality on actual organizational data. Public benchmarks cannot represent internal language, specialized code, document formats, or each system's acoustic environment.
Evaluate cross-modal search on the tasks you actually use
EmbeddingGemma 2 brings search and retrieval across text, code, images, video, and audio into a model designed for user devices. If on-device tools and hardware support improve, this approach may help apps organize personal data without sending all of it to external services.
Sources
- Google DeepMind: EmbeddingGemma 2: an open, lightweight multimodal embedding model
- Google Developers Blog: EmbeddingGemma 2: The Developer Guide
- Google AI for Developers: EmbeddingGemma 2 model card
- Google for Developers
This article references Google announcements and documentation as of 7 October 2026. Benchmark numbers and performance are reported by the developer and may vary based on hardware, software, and actual workload. This article provides general knowledge. It is not individual financial, investment, legal, or tax advice. Readers are urged to review the latest information and consider their own circumstances before making any decisions.